dsh-llm-codex
ChatGPT Codex login, sortable catalog, and Fast models for DeepSeek Harness 适合需要在 DSH 中使用 ChatGPT 官方账号及快速模型服务的用户。
同名パッケージの別リポジトリ
インストール
npx -p @deepseek-ai/dsh dsh plugin --profile web add github:NOirBRight/dsh-llm-codexドキュメント
README 全文を読む ↗Web configuration
Open Settings → LLM Providers → Codex. Sign in with ChatGPT starts the official ChatGPT OAuth flow, opens the system browser, and stores the session only on the Host at $DSH_HOME/codex-oauth.json (mode 0600). The card then shows usage limits. Sign out deletes that file. The browser never receives tokens.
The collapsed header first-paints the last successful quota from the shared browser cache; error, unsupported, and signed-out states paint no cached meter. Signing in, signing out, or an authoritative signed-out status purges the cache in every bundle copy, even without providerDirectory.
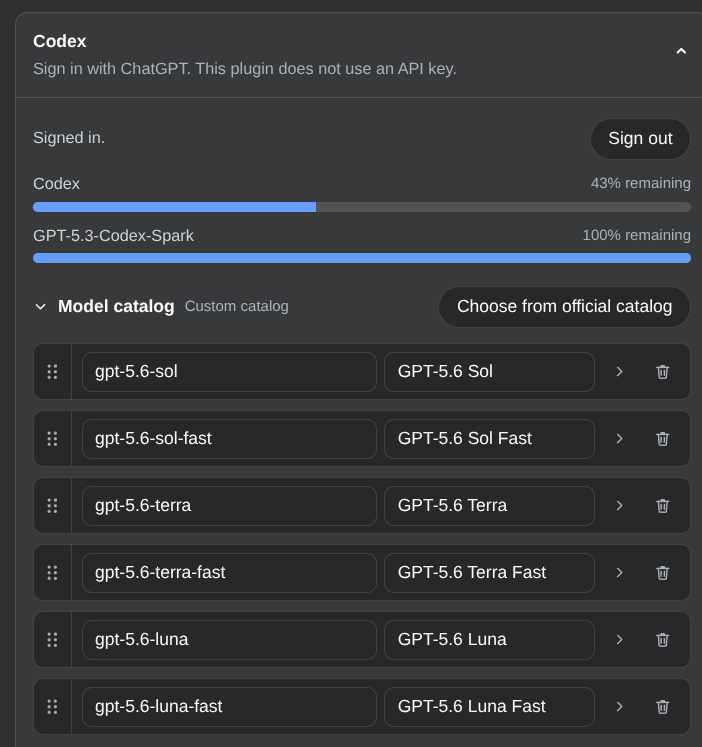
Model catalog
The conversation picker uses the displayed catalog stored as settings.models. The default is six rows:
gpt-5.6-sol/gpt-5.6-sol-fastgpt-5.6-terra/gpt-5.6-terra-fastgpt-5.6-luna/gpt-5.6-luna-fast
Fast and 1M are first-class picker rows, not checkboxes. Chat still uses the official wire id; Fast rows send service_tier: "priority". 1M rows (gpt-5.6-sol-1m, gpt-5.6-sol-1m-fast, and the Terra/Luna equivalents) set contextWindow to 1,000,000 so DSH compaction waits until 80% of that budget (800k). They are not in the default six-row catalog; add them from the official picker. The overlay can also add gpt-5.5, gpt-5.4, gpt-5.4-mini, gpt-5.3-codex-spark, and Fast variants. Custom ids can be added manually.
The official picker fetches the live account catalog using an unfiltered discovery client version; newer models (including gpt-6-sol and gpt-6-luna) appear without updating the static defaults. Choosing rows does not add them to conversations until saved. Offline, the last successful catalog is reused; discovery alone does not guarantee chat compatibility with future models.
Picker ids may also use a generic context suffix -k or -m (for example gpt-5.6-sol-272k or gpt-5.6-sol-272k-fast). The plugin peels that suffix before talking to ChatGPT and uses n×1000 / n×1,000,000 as the DSH compaction budget, so a 272K row starts compacting earlier than a 1M row. Product names such as kimi-k3-max are not treated as a context tier. The composer picker groups sibling rows that share a base id.
Default reasoning effort is per model and editable on the row: Luna uses max, Terra xhigh, Sol high, and every other official Codex model xhigh. Fast and 1M rows use their base model's default. A reasoning effort explicitly selected in a conversation takes precedence.
Chat goes through pi-ai openai-codex-responses against https://chatgpt.com/backend-api. Chat without a session fails MISSING_CREDENTIAL. A stored session whose refresh fails is reported as AUTH. A later content-less AUTH (HTTP 401) force-refreshes the session and retries the request once; remaining AUTH failures are eligible for the bundle's eight normal retries.
Remote compaction (not enabled)
The ChatGPT Codex Responses endpoint supports native V2 compaction: append compaction_trigger to a streaming request and replay the returned opaque compaction item in later requests. This is not the standalone /responses/compact API. DSH currently persists only a text summary as a user checkpoint through @deepseek-ai/dsh-compaction-basic; @deepseek-ai/dsh-llm-pi-ai does not pass opaque user-message metadata through to the Codex request. Calling V2 from this adapter alone would lose the item on the next turn or after a restart/branch. The plugin leaves remote compaction off and continues using DSH's existing local compaction.
Upstream seam needed: let a provider-specific compaction handler return an opaque, provider-scoped replacement history; persist it atomically with the compaction checkpoint and pass it back to the same provider on subsequent requests, including resume and branch. The Host must retain ownership of history trimming, cancellation, and fallback to text summarization when the provider/model does not support V2. The pi-ai bridge must serialize the opaque item unchanged rather than converting it to user text. Until this is available in an official DSH release, the plugin must not advertise or enable remote compaction.
Acceptance requires checking the next wire request for the encrypted item and retained user turns (and the discarded turns' absence), then repeating after resume/branch; a mocked usage value or prompt_cache_key alone does not prove cache reuse. With a stable session/routing identity and a shared prefix of at least 1,024 tokens, check the provider's usage.input_tokens_details.cached_tokens on repeated post-compaction requests. Compare that count to the measured token position before the opaque item: a hit confined to instructions does not demonstrate reuse of the compressed history. A lab-only Codex protocol probe completed V2 and replay; the pre-item request used 3,318 input tokens, while repeated continuation requests reported 3,328, 3,200, and 0 cached tokens. Cache hits are provider-dependent, and plugin-level 3082 acceptance remains blocked on the upstream seam. See OpenAI prompt caching and compaction.
Model Switch integration
When dsh-model-switch v0.2+ is present, Codex registers optional Search and Image adapters that reuse this plugin's authenticated clients. Model Switch keeps official web_search ownership and leaves view_image / codex_generate_image unchanged. No Vision adapter is registered.
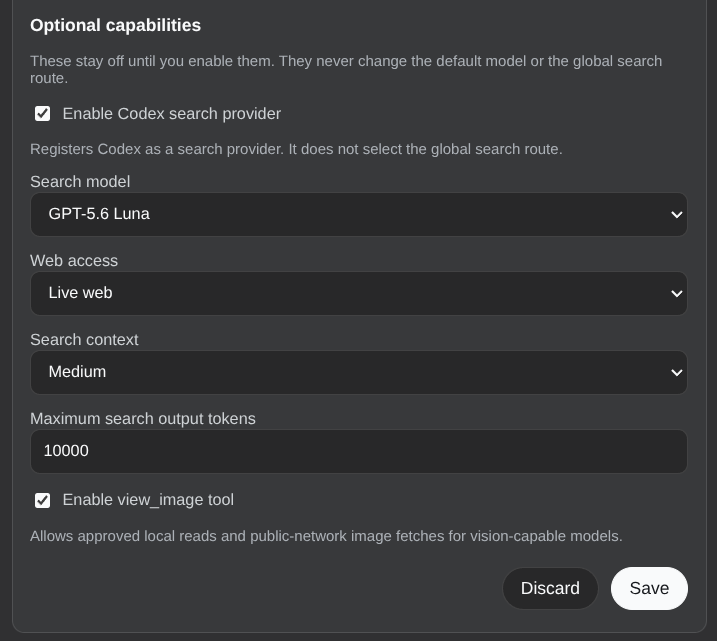
Optional capabilities
Search, view_image, and codex_generate_image are implemented but default off. Enabling any of them and clicking Save registers or unregisters it immediately; no restart is required. Search registers a standalone Codex WebSearchProvider (POST /codex/alpha/search). It does not write web.searchProvider or agent-default-model. The search-model dropdown lists official non-Fast models and defaults to gpt-5.6-luna. The plugin also registers web/openai-codex-search-llm-request so session logs written by dsh-codex-connect remain readable after that plugin is uninstalled. Search modes match official Codex:
cached(default): OpenAI-maintained index, no live fetchindexed: live fetch only when the search index gates the requestlive: unrestricted live retrieval
view_image is a model-invoked tool for local files and public-network HTTP(S) images. Spark is text-only.
codex_generate_image is a separate model-invoked tool. Any conversation model can call it; it uses this plugin's ChatGPT login and Codex usage (typically 3–5× a text turn) and draws with backend gpt-image-2. The routing-model dropdown lists official vision models and defaults to gpt-5.6-luna. The name is intentionally not generate_image, so it does not collide with other provider plugins. Generated files land under generated-images/ unless path is set.