vitas/dsh-jev-subagent-dispatch ↗★ 0
dsh-jev-subagent-dispatch
Cut LLM costs: route routine tasks to cheap subagent models (DeepSeek Harness plugin) 适合有大量日常任务、希望通过智能分流降低大模型API调用成本的用户。
インストール
npx -p @deepseek-ai/dsh dsh plugin --profile web add github:vitas/dsh-jev-subagent-dispatchドキュメント
README 全文を読む ↗dsh-jev-subagent-dispatch
Cut LLM costs: routine tasks go to cheap subagent models; the main model keeps the hard parts.
Jev-guided subagent dispatch for DeepSeek Harness: the plugin asks Jev — TypeSafe's typed-decision model — a handful of atomic questions about the task, applies your routing policy, and appends a dispatch recommendation: which subagent model route should take the turn. The division of labor is deliberate — Jev guides, the main agent performs the handoff through the harness-native subagent tool; the plugin owns no delegation machinery of its own.
Jev does not write code and is not a chat LLM. It answers typed questions (choice / score / noul) with probabilities and a confidence, in one parallel pass, in tens of milliseconds. That makes it an ideal guide: the expensive main agent stops spending tokens deciding who should do the work.
[jev-subagent-dispatch]is to your agent what a team lead is to a developer: it reads the ticket for 200 ms and decides whether it goes to a junior — and it never lets a junior touch production.
The injection is advice, not enforcement: the main agent weighs it and can ignore it. Measure the recommendation's quality (see Measuring impact) before trusting it in daily work.
At a glance
The Subagent plugin has to be active. Delegation is not something this plugin can provide: DSH composes the subagent service, a child provider behind it, and the subagent tool separately, and this package deliberately takes no dependency on any of them — it re-checks at request time instead, and the card warns you when the plugin's absence is visible from settings. With it off, a verdict is still produced; there is simply nowhere to send it.
Its routes must name models your session allowlist permits. A route the allowlist forbids still classifies, so the verdict reads as healthy while dispatch is impossible. The card removes the trap: one select per role, offering exactly the allowlisted models.
| Jev's task class | Role that takes it | Shipped route | Delegated |
|---|---|---|---|
mechanical — renames, reformatting, comments, boilerplate | junior | openrouter/qwen3.8-flash | yes |
bugfix | implementer | openrouter/deepseek-v4-flash | yes |
research | researcher | openrouter/qwen3.8-flash | yes |
review — a second opinion on work that already exists | reviewer | openrouter/qwen3.8-flash | yes |
refactor, feature_work, meta_chat | — | — | no — absent from profiles.*.delegate.taskClass, so they never reach a route |
Delegated is the shipped auto profile. The stricter careful profile delegates only mechanical, and the predicate's ceilings (effort, blast radius, per-question probabilities) can hold any class back regardless of its role.
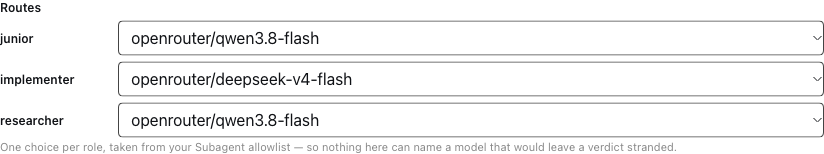
Roles name the worker, classes name the work. routeFor maps a class to a role and routes maps a role to a model, so you can add a role, or point an existing one at a different model, without touching the rubric. junior exists because mechanical and bugfix are delegated together but are not one job — a rename has an unambiguous spec, a bug fix has to find the cause first — and it is the role to point at your cheapest model. reviewer ships on the same example gateway as the others, because which models exist is your composition's business and not this plugin's: the one thing the role asks of whoever configures it is that it points at a different model than your implementer — a second opinion from the model that wrote the change, or from its twin, is worth less. Every shipped route is a placeholder you replace with one select in the card; a route that is not composed fails loudly, naming the role.
Everything below is the detail behind those facts; the failure modes are in Dispatch capability is a prerequisite.
Dispatch capability is a prerequisite
For a dispatch plugin, calling Jev before knowing whether the agent can delegate at all would waste the call. DSH needs three pieces for delegation — the subagent service, a child provider behind it, and a delegation tool visible to the agent — and a depth limit of 0 disables delegation entirely. Installing this plugin implies none of that, so every routing request re-verifies capability at request time against the live host services (never a package dependency, never a boot-time snapshot):
- a delegation tool (
subagent/subagent_fork) is visible to this agent; - the subagent service is present and the provider behind the visible tool is registered;
- the agent has remaining delegation depth (
session.header.delegationDepthagainst the effective depth limit — provider-managed limits always leave room locally); - the session's model-selection policy (
subagentModelSelectionPolicyprojection): when model selection is off, the subagent tool takes no model argument and the recommendation names no model — the session's configured child default applies; when it is on, a configured route is named only if the session allowlist contains it, otherwise the message points the agent atlist_subagent_models; - which tool, and its provider: a fork is fixed-route no matter what the tool is called — the advice renders as "the fork inherits your model and context" for
subagent_forkand for a custom-named tool withprovider: forkalike. A model name is only ever advice the visible tool can follow.
| Situation | Explicit /route request | Ordinary turn (auto) |
|---|---|---|
| Capability check passes | classify → inject recommendation | classify → inject recommendation |
| Capability check fails | inject a diagnostic naming what is missing; no Jev call | fully silent — no injection, no call, no log line |
| The Jev call itself fails (timeout, rejected key, HTTP error) | inject a one-line diagnostic naming the failure; the turn proceeds unrouted | fully silent — the turn proceeds unrouted |
Changes to session or plugin setup take effect on the next request — nothing is cached from boot.
The settings card carries a lighter, earlier version of the same check: it reads the Subagent plugin's own settings namespace, which the loader serves only while that row is composed and enabled, and shows a warning when it is gone. That catches the one case you would otherwise meet as a verdict with nowhere to go — a profile where the plugin was never enabled. It is a probe, not the authority: only the request-time check above sees the session's tool visibility, which is why a missing namespace warns while a depth-limited or tool-disabled session still reports itself through the diagnostic message.
Modes: Jev runs when you ask, not on every turn
The default is off — nothing is registered, nothing is shared. Three activation models, cheapest first:
| Mode | How it works | Trade-off |
|---|---|---|
off (default) | No pre-step listener at all. | Zero cost, zero data sharing; you must configure more to get value. |
once | Only turns that explicitly ask are classified: /route fix the failing tests calls Jev once; every other turn passes through untouched. | Predictable cost and data sharing, but you must remember to ask. |
auto | Every plain user turn is considered (the original behavior). | No user effort, but enable it only when the verdict log shows the recommendations earn their place. |
Trigger syntax (configurable via triggers):
/route fix the failing tests        → one Jev call, a routing recommendation
/jev should I delegate this?        → free-form decision request to the rubric
/route preview rename everything    → evaluation-only verdict (see below)
A request may name the decision: the text after the trigger leads the state sent to Jev (/jev which specialist? becomes a decision request the typed rubric answers through its vocabulary). This makes Jev a small decision service the agent can reuse, while the routing policy remains one specific use of it.
Preview — /route preview classifies and injects an evaluation-only verdict: full answers — including score distributions (blast_radius distribution: trivial 0.20, …) so the risk policy can be tuned against real mass — an explicit "do not delegate based on this", and a trigger: preview mark in the verdict log. Misses are rendered too: a verdict the policy declines injects verdict: skip — with its answers, because the skipped cases are exactly the ones you cannot see any other way. Collect real examples this way and read them against actual outcomes before allowing automatic delegation.
Roadmap, in the order the evidence would justify it: an agent-called route_task tool (the main agent asks when unsure — natural in conversation, but it still spends a step deciding to call), and selective auto (cheap local rules first, Jev only for turns whose route stays unclear — needs collected data to tune the trigger).
How a turn flows
user message ──▶ agent/pre-step waterfall
                   │
                   ├─ downstream listeners (memory plugins, …) run first
                   │
                   └─ jev-subagent-dispatch (prepended, sees the final batch)
                        ├─ mode gate: off → never; once → only /route, /jev turns
                        ├─ capability gate: delegation tool + provider + depth
                        ├─ build state: redacted turn + explicit request, capped
                        ├─ POST {provider endpoint}{apiPath} (6 atomic questions, one call)
                        ├─ apply profile policy (predicate + confidence gates)
                        ├─ log verdict to NDJSON (opt-in)
                        └─ "delegate" verdict? append a routing recommendation
                              ▼
        main agent spawns the recommended subagent (harness-native tool)
Fail-open everywhere: a missing key, a timeout, a 429, or a broken config logs the reason and the turn proceeds unrouted. The plugin injects only when it is confident; otherwise it stays silent.
Privacy
The state sent to TypeSafe is deliberately minimal and is redacted before it leaves the machine:
- the user's turn text plus a
workspace:line — no diffs, no tool output, no file contents; - the task text leads the state and the workspace path trails as bounded context (≤ 120 chars) — the whole assembled payload is redacted (the path passes the same credential filters as the task text) and capped to
stateChars(default 1200) as a whole, so no path length can leak, exceed the cap, or push the task out; - credential-shaped substrings (
sk-…,ghp_…,github_pat_…,AKIA…,Bearer …,api_key=…, long base64 tokens) are replaced with[redacted]by built-in patterns;redactPatternsadds your own regex sources; - logging is opt-in (
logDir), and the user's turn text reaches the log only whenlogTurnTextis true — the verdict itself (class, scores, probabilities, route, usage) is what you calibrate against.
Sending task text to TypeSafe is the point of the plugin; if that is unacceptable for a repository, set enabled: false for it.
The rubric (what gets decided)
The questions config mirrors TypeSafe's documented request shape exactly — a map keyed by question id, each entry carrying type, instructions, and criteria — so what is configured is what goes on the wire. Six atomic questions in one request; adding questions does not add latency:
| Question | Type | Criteria |
|---|---|---|
task_class | choice (map of option → description) | mechanical · bugfix · feature_work · refactor · research · meta_chat |
effort | score (ordered level array) | S (0) · M (1) · L (2) · XL (3) |
blast_radius | score (ordered level array) | trivial (0) · module (1) · cross_module (2) · public_api (3) · infra (4) |
needs_repo_context | noul | probability the task spans several repo modules |
user_explicit | noul | probability the user asked the main agent to do it personally |
risky | noul | probability the task touches secrets, migrations, infra, destructive ops |
A Choice answer names the selected option (choice) with per-option probabilities. A Score answer is a numeric position on the levels spectrum (0..n-1) that may land between two levels — 1.4 means "between M and L" — with a probability per level. A Noul answer is a single 0..1 probability.
The policy (how it decides)
activeProfile: auto
profiles:
  auto:
    confidenceMin: 0.7
    delegate:
      taskClass: [mechanical, bugfix, research]
      effortMax: 1.5          # up to "between M and L"
      blastRadiusMax: 1.5     # up to "between module and cross_module"
      maxNoul:
        needs_repo_context: 0.5
        user_explicit: 0.3
        risky: 0.2
      # cap the probability of a severe level, not only the average score;
      # levels are rubric names (structured criteria entries are addressed
      # by index), "name+" sums that level and everything worse; an
      # incomplete score distribution fails the gate closed
      probabilityMax:
        blast_radius: { "public_api+": 0.15, infra: 0.05 }
routeFor:            # task class → role that takes it
  mechanical: junior  # roles name the worker; the class keeps its own name
  bugfix: implementer
  research: researcher
  review: reviewer
routes:              # role → the model that role runs on
  junior:      { provider: openrouter, model: qwen3.8-flash }
  implementer: { provider: openrouter, model: deepseek-v4-flash }
  researcher:  { provider: openrouter, model: qwen3.8-flash }
  reviewer:    { provider: openrouter, model: qwen3.8-flash }
Delegation is recommended only when all of it holds: the declarative predicate over the answers (score ≤ ceiling, so boundary values pass; a missing answer fails closed), and the primary confidence above the profile floor. Two shipped profiles: auto delegates readily; careful (confidence 0.85, effort ≤ 0.5, blast radius ≤ 0.5) for repositories where a wrong delegation is expensive. Tune coefficients in config, not prompts. If you would rather gate on the probability of exceeding a level than on the numeric score, read probabilities from the score answer — the log records them per turn.
The routes mirror the allowlist in Settings → Subagent → "Models agents may choose" — the plugin owns no delegation machinery; the harness-native subagent tool spawns with the recommended provider/model.
Providers: where your Jev access lives
The key's issuer determines the endpoint, the API path, the credential variable, and the pinned model id. One shared question format and routing policy sits on top; the provider preset swaps only the wire address and model:
| Key from | provider | Jev endpoint | Pinned model | Key env |
|---|---|---|---|---|
| B.AI | bai | https://api.b.ai/v1/decisions | jev-1.13.0 | OPENROUTER_API_KEY |
| OpenRouter | openrouter | https://openrouter.ai/api/v1/systemone | jev-1.13 | OPENROUTER_API_KEY |
| TypeSafe | typesafe (default) | https://api.typesafe.ai/v1/systemone | jev-1.13.0 | TYPESAFE_API_KEY |
B.AI's Decisions API and OpenRouter's System One API both return typed Jev answers in the same shape; the plugin sends the identical rubric and applies the identical policy regardless of provider. Explicit endpoint, apiPath, apiKeyEnv, or model values in the row config override the preset — so a self-hosted or proxied Jev endpoint needs only those four strings. If your key came from B.AI, set provider: bai and you are done. An inherited value stays blank in the card, which shows the preset's value a