Grivn/mnemon-memory-agent ↗★ 2
dsh-mnemon
提供包含运行上下文、文档检索及长期记忆的控制系统 适合需要为大模型助手构建长期记忆、处理复杂双系统思考任务的用户。
同名包的其他仓库
安装
npx -p @deepseek-ai/dsh dsh plugin --profile web add github:Grivn/mnemon-memory-agent说明文档
阅读完整 README ↗Mnemon
Raw Records, Fast Judgments, Slow Thoughts
Paper · Results · Reproduce · Run · 中文
Mnemon is a long-term memory agent for LLM assistants. It keeps conversations as raw, dated records and does its work when a question arrives, dividing that work the way dual-process accounts divide thinking. A fast decision model (System 1) makes many small yes/no judgments about the records the searches return. An LLM (System 2) writes a few search queries, names what the reply needs and composes the answer. A background pass consolidates each record once into an index that points back to the records, so that questions about a whole conversation reach evidence their own searches miss. The results of this research will be brought step by step into the official projects mnemon and dsh-mnemon (see From research to product).
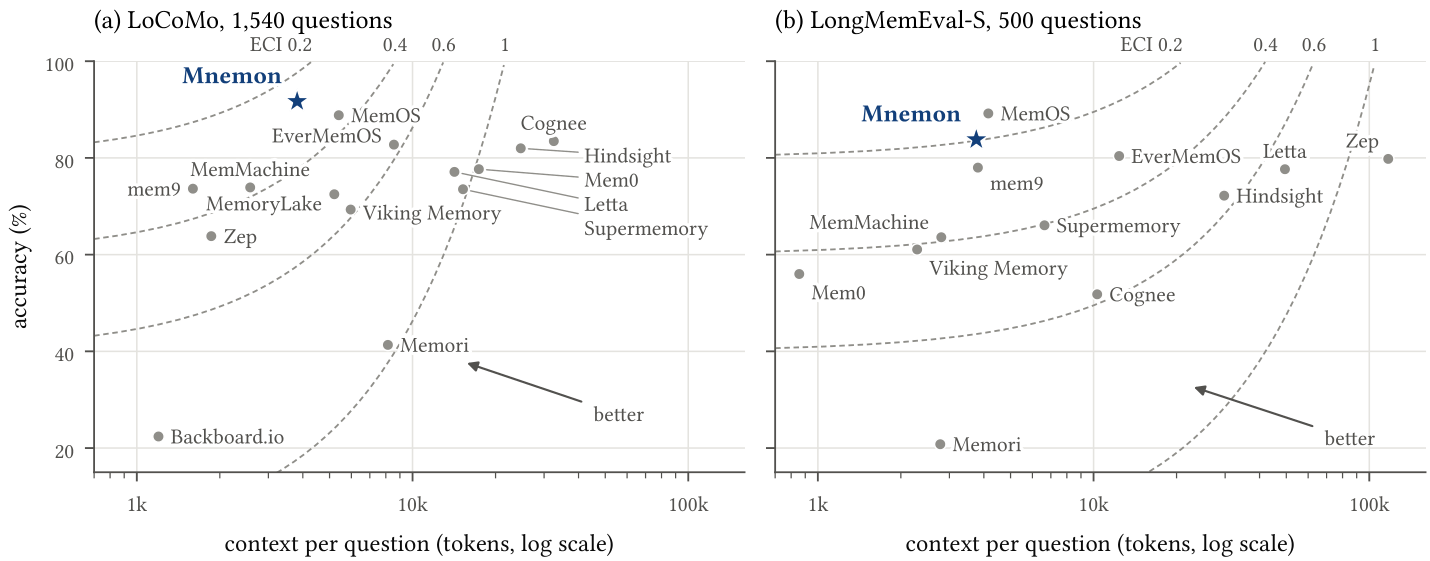
Accuracy against the context sent to the answering model per question. Mnemon (star) and the 14 systems re-evaluated by OmniMemEval all use gpt-4.1-mini to answer. Dashed lines join points of equal effective cost index; up and to the left is better.
Highlights
- Most accurate on LoCoMo, from under 4k tokens of context. Compared with the 14 systems OmniMemEval re-evaluated, all with gpt-4.1-mini answering, Mnemon scores 91.7% on LoCoMo (first of 15 systems) and 83.8% on LongMemEval-S (second of 13). It sends the answering model about 3.8k tokens per question. It is the only system above 80% on both benchmarks below 4k tokens.
- Lowest effective cost index on LoCoMo: 0.259, against 0.337 for the next system.
- On par with the best published results on LongMemEval-S. With DeepSeek-V4.1-Flash as System 2, Mnemon reaches 94.4% on LongMemEval-S and 92.2% on LoCoMo (95.3% on revised labels).
- Bounded cost at 10M tokens. From BEAM-100K to BEAM-10M, with 80 times as many records, the cost per question grows by a factor of 1.11, and the work on a question's critical path stays about the same.
- System 1 judges better. On the same 14,359 records, Jev separates gold evidence with an AUC of 0.942. DeepSeek reaches 0.900 and gpt-4.1-mini 0.853, at 3–11 times Jev's latency.
- Raw records beat a write-time graph built by the same model. Under one protocol, Jev-Mem, which uses Jev to organize memory into a graph as turns are written, scores 84.4% on LoCoMo against Mnemon's 91.7% (7.3 points, 95% CI 5.5–9.2).
Approach
Fast judgments, slow thoughts
Most of the read-time work of memory is System 1 work: small, independent yes/no judgments with explicit criteria.
- Should the reply use this record?
- Is it no longer current?
- Does it give the second of the two dates the question needs?
A decision model such as Jev makes dozens of these judgments in a third of a second.
Only a little is System 2 work: writing a few search queries, naming what the reply needs and composing the answer. An LLM does this well but slowly.
Because the judging is fast, Mnemon can afford to read raw records when a question arrives instead of rewriting them in advance. The rules between the two systems read only what System 1 reliably gives: its ranking and its yes/no decision. They call on System 2 only when no judged record satisfies a need.
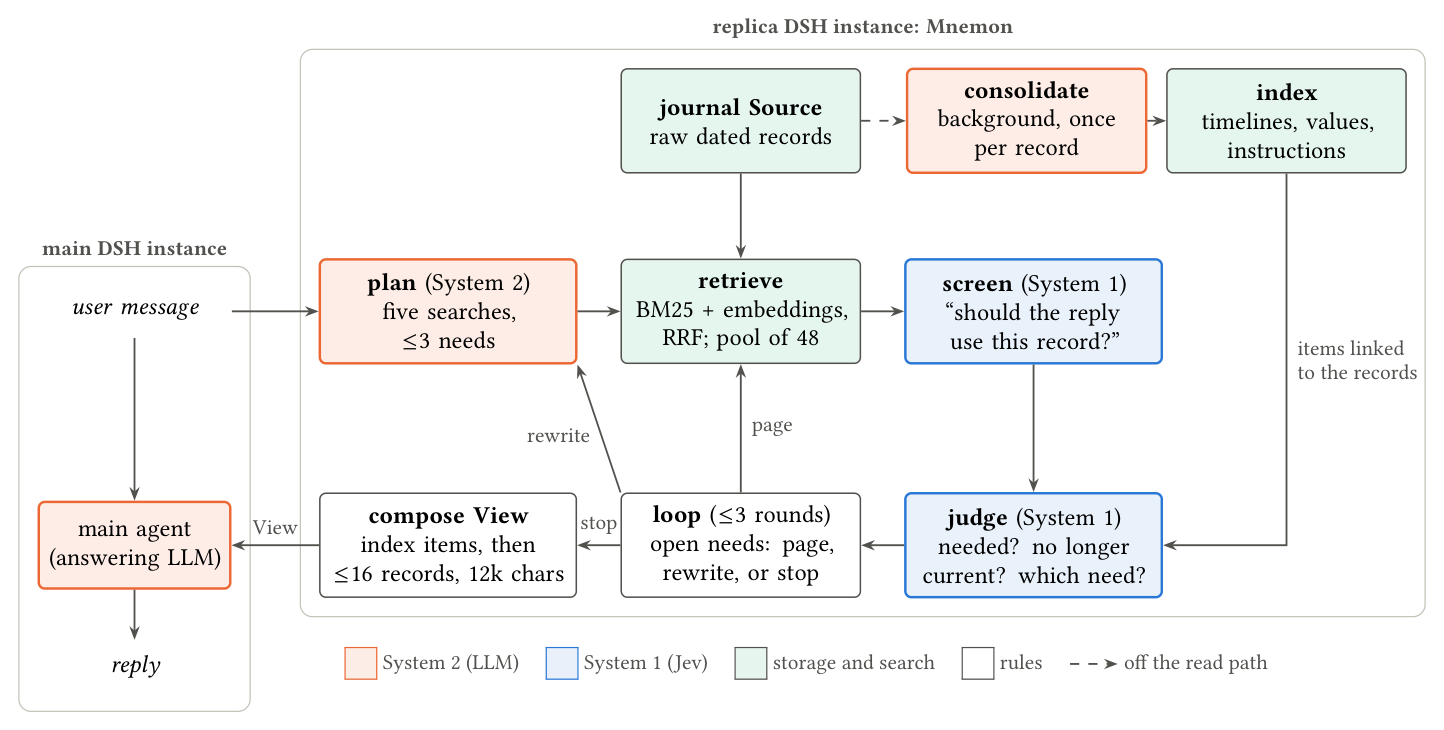
Mnemon at one user turn. It runs as a second instance of DeepSeek Harness beside the main agent, which it leaves unchanged, and publishes one View per turn.
Memory without a write-time schema
Systems that extract at write time must decide in advance what counts as a fact, an entity or a preference. Each new kind of data then needs a new extraction schema. Mnemon decides nothing about a record when it is written, so it needs from a store only a search route that returns dated records.
The consolidated index (topic timelines, value histories, standing instructions) sits on top of the records and points back to them. It is an overlay on the records, not their schema. Mnemon reads the records with or without it.
Keeping records raw also lets the memory grow without rewriting what is stored. A record can be searched as soon as it is embedded; organizing runs in the background and can be redone from the records. Longer histories, stronger answering models and new rules apply to everything already stored.
Memory of this kind can be added wherever records can be searched. The paper evaluates conversational memory, the setting with public benchmarks; other stores are untested.
Results
All numbers come from docs/paper/data/results.json, which is computed from the run records in runs/. Our runs
are graded by gpt-4.1-mini and DeepSeek-V4.1-Flash; OmniMemEval grades with gpt-4o-mini, a grader difference of 1–2
points.
Under one protocol (gpt-4.1-mini answering)
Accuracy (%), context sent to the answering model per question, and the effective cost index. The index is ECI = (1 − accuracy) + context / full-context tokens: the expected cost of a question when each error is repaired by one full-context answer. Lower is better. Other systems' numbers are OmniMemEval's.
| System | LoCoMo | context | ECI | LongMemEval-S | context | ECI |
|---|---|---|---|---|---|---|
| Mnemon | 91.7 | 3.8k | 0.259 | 83.8 | 3.8k | 0.198 |
| MemOS | 88.83 | 5.4k | 0.362 | 89.2 | 4.2k | 0.147 |
| Cognee | 83.48 | 32.5k | 1.670 | 51.8 | 10.3k | 0.580 |
| EverMemOS | 82.75 | 8.6k | 0.569 | 80.4 | 12.4k | 0.314 |
| Hindsight | 81.99 | 24.7k | 1.322 | 72.2 | 29.8k | 0.561 |
| Mem0 | 77.68 | 17.4k | 1.028 | 56.0 | 0.9k | 0.448 |
| Letta | 77.12 | 14.2k | 0.885 | 77.67 | 49.4k | 0.693 |
| MemMachine | 73.9 | 2.6k | 0.380 | 63.6 | 2.8k | 0.391 |
| mem9 | 73.64 | 1.6k | 0.337 | 78.0 | 3.8k | 0.256 |
| Supermemory | 73.53 | 15.2k | 0.970 | 66.07 | 6.6k | 0.402 |
| MemoryLake | 72.49 | 5.2k | 0.516 | – | – | – |
| Viking Memory | 69.33 | 6.0k | 0.583 | 61.07 | 2.3k | 0.411 |
| Zep | 63.83 | 1.9k | 0.448 | 79.8 | 117.1k | 1.316 |
| Memori | 41.34 | 8.1k | 0.963 | 20.8 | 2.8k | 0.818 |
| Backboard.io | 22.4 | 1.2k | 0.831 | – | – | – |
Only the context sent to the answering model is compared, because it is the one cost every system reports. Mnemon's other costs (planner, Jev, consolidation) are listed below and are not folded into the index.
Against each project's best published result
Each project's best claim, with whatever answering model, grader and protocol it used. The settings differ widely, so this ranks claims, not systems. The paper's Table 3 has all 20 entries and their sources.
| Project | LoCoMo | LongMemEval-S | Answering model / grader |
|---|---|---|---|
| Mnemon | 95.3† | 94.4 | DeepSeek-V4.1-Flash (thinking) / DeepSeek |
| Zep / Graphiti | 94.7 | 90.2 | gpt-5.4 (medium reasoning) / gpt-5.4 |
| EverMemOS | 93.05 | 83.0 | gpt-4.1-mini / three graders averaged |
| Mem0 | 92.5 | 94.4 | gpt-5 / gpt-5 |
| memU | 92.09 | – | not stated (early version) |
| Hindsight | 92.0 | 94.6 | not stated (paper: gemini-3-pro 89.6 / 91.4) |
| MemMachine | 91.69 | 93.0 | gpt-4.1-mini; LongMemEval-S gpt-5-mini / gpt-4o-mini |
| MemOS | 88.83 | 89.2 | gpt-4.1-mini / gpt-4o-mini (OmniMemEval) |
† On the revised LoCoMo labels, which drop 44 unusable questions and correct 25 answers; 92.2 on the original labels, which every other entry uses.
Every benchmark and tier, with the full cost
gpt-4.1-mini answering. Score under the gpt-4.1-mini / DeepSeek graders (accuracy; HaluMem: share correct; BEAM: rubric score). The rank is among the systems OmniMemEval re-evaluated. Cost per 1,000 questions covers the answer, the planner and Jev at list prices; consolidation is a one-time cost per history. Jev calls (sequential waves) and searches are the median question's; the last column is the warm latency of one search on the largest history.
| Benchmark | Score | Rank | Context | Cost / 1k questions | Consolidation / history | Jev calls (waves) | Searches | Search |
|---|---|---|---|---|---|---|---|---|
| LoCoMo | 91.7 / 91.4 | 1/15 | 3.8k | $3.27 | $0.013 | 5 (4) | 7 | 14 ms |
| LongMemEval‑S | 83.8 / 85.4 | 2/13 | 3.8k | $3.33 | $0.017 | 5 (5) | 7 | 14 ms |
| HaluMem | 73.3 / 65.8 | 8/13 | 3.4k | $3.60 | $0.089 | 7 (6) | 10 | 18 ms |
| BEAM‑100K | 64.5 / 60.5 | 10/12 | 3.8k | $4.80 | $0.012 | 9 (7) | 13 | 17 ms |
| BEAM‑10M | 51.2 / 48.8 | 10/12 | 3.8k | $5.32 | $1.62 | 10 (7) | 14 | 248 ms |
Nothing on the read path grows with the history except the search index. The planner reads the recent dialogue, Jev screens at most 48 records a round, and the View has fixed budgets. System 1 does the broad reading: per question, Jev reads 35–73k tokens of records, 9–19 times what the answering model reads, at about a tenth of its price per token.
Work per question. Our runs shared one laptop and public model APIs, so we state latency as critical-path work (medians):
- System 2 plans once, with two calls in parallel, and answers once; a question whose loop asks for a new search (6–31% of them) makes one more call.
- System 1 makes 5–10 Jev calls in 4–7 sequential waves of about 0.34 s each: 1.4–2.4 s in all.
- A warm search takes 14–18 ms, mostly to embed the query, and all of a question's reads of the journal 0.1–0.2 s.
These counts stay about the same from BEAM-100K to BEAM-10M. Only the search grows with the history, to 248 ms a search and 3.5 s of reads a question on BEAM-10M's largest history (108,810 records), because it scores every record; inverted and approximate nearest-neighbor indexes would avoid this.
System 1 against LLMs
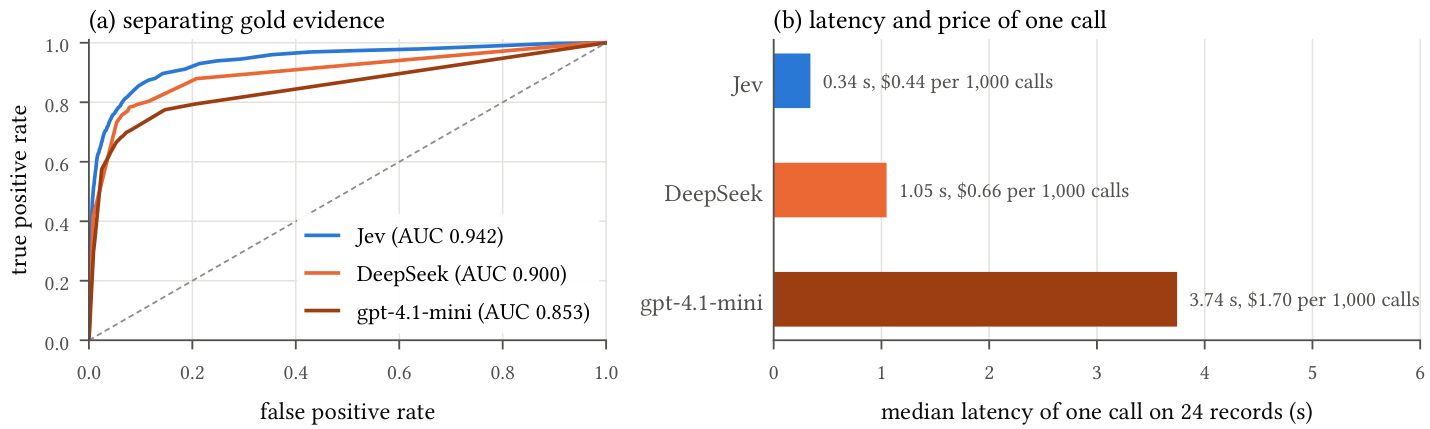
Jev, DeepSeek and gpt-4.1-mini judged the same proposition about each of the same 14,359 records. Jev separates the gold evidence best and answers two propositions per record in the time an LLM takes for one.
Raw records or a write-time graph, with the same Jev
Jev-Mem, concurrent work, uses Jev at write time: it types each turn and links it into a relation graph, then steers retrieval over that graph. We ran its released code under our protocol: the same 1,540 LoCoMo questions, gpt-4.1-mini answering once per question from the question alone, and both graders. (Its released runner, by default, picks the best of three answers against the gold answer; we did not.)
| LoCoMo, gpt-4.1-mini answering | Mnemon | Jev-Mem |
|---|---|---|
| accuracy, gpt-4.1-mini grader | 91.7 | 84.4 |
| accuracy, DeepSeek grader | 91.4 | 82.1 |
| multi-hop / temporal (gpt-4.1-mini grader) | 91.8 / 91.3 | 77.7 / 82.9 |
| context per question | 3.8k | 2.6k |
| write-time cost per history | $0.013 | $0.12 |
The paired difference is 7.3 points (95% CI 5.5–9.2). Given each question's category, Jev-Mem scores 84.0%. The two
systems differ in more than where Jev works, so this is not an ablation, but with the decision model held fixed,
judging raw records once the question is known was the more accurate. The adapter is
docs/paper/scripts/jevmem_locomo.py, and the run records are in runs/jevmem-locomo-20260928.
Components and versions
Mnemon is the research branch codex/jev-replica-practice of dsh-mnemon.
It was forked from the dsh-mnemon release v0.5.13 (commit 84d469ff, 2026-09-22) and developed over 225 commits
up to this snapshot, 50a6831d. It runs on DeepSeek Harness 0.1.5-rc.1, which it does not modify. Apart from 115
changed lines in dsh-mnemon's existing code, the memory agent consists of new plugins.
| Component | Version | Role in Mnemon |
|---|---|---|
| dsh-mnemon | v0.5.13 + 225 research commits (50a6831d) | memory plugins, the replica and the benchmark harness |
| DeepSeek Harness (DSH) | 0.1.5-rc.1 | agent harness; Mnemon runs as a second instance beside the main agent |
| Jev (TypeSafe System One) | jev-1.13.0, through @typesafe-ai/sdk 0.6.0 | System 1: screens and judges records and index items |
| gpt-4.1-mini | 2025-04-14 snapshot, temperature 0 | System 2 in the standard setting (planner and answering model); grader, primary in the standard setting |
| DeepSeek-V4.1-Flash | API model deepseek-flash | System 2 in the reasoning setting (answers with thinking, plans without); consolidation, without thinking; grader, primary in the reasoning setting |
| nomic-embed-text | served locally | embeddings for hybrid search and index items |
| Node.js / pnpm | v25.1.0 / 11 | runtime and package manager |
Each run directory records the commit and the models it ran with (docs/run-commits.json); VERSIONS.md
lists every version, including the build tools and the datasets.
Reproduce the numbers
Every number in the paper comes from docs/paper/scripts/collect.py, which reads the run records. No API keys are
needed.
python3 tools/restore_runs.py                     # expands runs/ into runs-expanded/ and checks every file
# Put the two public datasets beside them:
#   runs-expanded/benchmarks/locomo10.json              LoCoMo, from github.com/snap-research/locomo
#   runs-expanded/benchmarks/longmemeval_s_cleaned.json LongMemEval-S (cleaned), from the LongMemEval release
MNEMON_RUNS=$PWD/runs-expanded python3 docs/paper/scripts/collect.py   # rewrites docs/paper/data/results.json
git diff --stat docs/paper/data/results.json      # no change: the records reproduce the committed numbers
TECTONIC=tectonic PYTHON=python3 bash docs/paper/build.sh   # tables, figures (matplotlib) and main.pdf
python3 docs/paper/scripts/arxiv.py --out out/arxiv         # arXiv source package (pdfLaTeX, TeX Live 2025)
HaluMem's run records are not included (see DATA-LICENSES.md). Without them, collect.py
keeps the committed HaluMem entries, so those numbers cannot be recomputed here; every other number can.
beam_evidence.py additionally needs pyarrow and BEAM's 100K.parquet. work.py and retrieval.ts, which
measure the work per question, read the replica traces and journals, which this snapshot does not include; their
results are in docs/paper/data/.
Run the system
Requirements: Node.js 25 (the runs used v25.1.0) and pnpm 11.
pnpm install --frozen-lockfile        # installs DSH 0.1.5-rc.1 exactly as the runs did
pnpm run build && pnpm run build:plugins
pnpm -r --filter 'dsh-mnemon-*' test --passWithNoTests
Live runs call external models. Provide the keys in the environment or in a local .env (git-ignored), never in
the repository:
| Variable | For |
|---|---|
TYPESAFE_API_KEY | Jev (System 1) |
DEEPSEEK_API_KEY | DeepSeek answering, planning, notes and consolidation |
OPENAI_API_KEY | gpt-4.1-mini runs and judging |
OPENAI_BASE_URL | optional; defaults to the OpenAI API |
A two-question smoke run of the final configuration's core:
n